Logo Theo Sourget
  • Home
  • About
  • Experiences
  • Education
  • Publications
  • More
    Projects Skills Recent Posts
  • Posts
  • Dark Theme
    Light Theme Dark Theme System Theme
Logo Inverted Logo
  • Posts
  • My Research
    • Citation needed
    • Dataset Diversity Metrics
  • Other
    • Build Apps with Streamlit, FastAPI and Docker
Hero Image
Dataset Diversity Metrics and Impact on Classification Models​

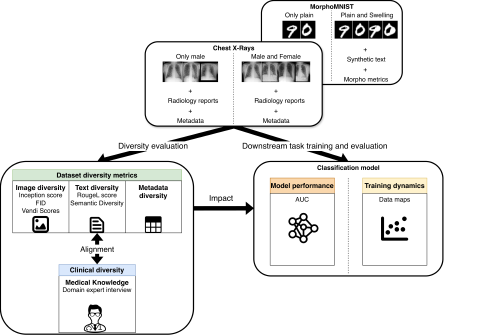
Diversity is commonly viewed as a good and important feature for a dataset, as a large and diverse dataset should lead to better results and generalization. However, while datasets are often claimed to be diverse, what “diverse” is, is not clearly defined and may change from paper to paper. It could, for example, refer to the demographics of the patients, the scanner being used, the annotators, etc. There are some metrics to quantitatively measure the diversity of a set, they are however mostly used in a generative context such as image generation or answers from LLMs. Their usage on real datasets and their correlation with a downstream performance task is therefore unclear. Finally, while datasets are increasingly multimodal, for example containing chest X-rays and radiology reports with metadata, most studies only assess the diversity of a single modality for a dataset.
    Sunday, September 13, 2026 Read
    Hero Image
    Create your own applications with Streamlit, FastAPI and Docker​

    During my projects, I like to build concrete applications from the research I conduct. I use them to demonstrate the capacity of a trained model or a pipeline I developed but also use the code in a more general purpose. To build these apps I use a combination of three tools: Streamlit, FastAPI, and Docker. In this post, I first show two examples of applications I’ve created, and then I present the tools with some simple examples of code.

      Sunday, April 20, 2025 Read
      Hero Image
      [Citation needed] Data usage and citation practices in medical imaging conferences​

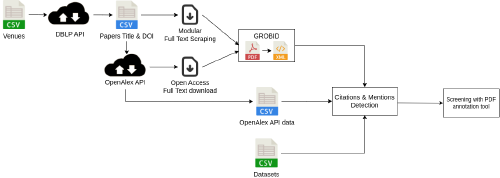
      Click on the image below to see my oral session at MIDL 2024: Nowadays, the evaluation of models heavily relies on publicly available datasets used as benchmarking. While this could be a nice thing for a fair comparison of different models, we also question the effect of the diversity or more precisely a potential lack of diversity in research papers when selecting the datasets. A gap has been observed between the results showcased by AI models in research and their adoption in clinical workflow, we hypothesise that this gap could partly be a result of an overfitting of research on these datasets and we wanted to evaluate their usage to know if some are more popular than others. While this could seem like a straightforward task we’ll see that because of some elements it turned out to be not so simple.

        Tuesday, July 9, 2024 Read
        Navigation
        • About
        • Experiences
        • Education
        • Publications
        • Projects
        • Skills
        • Recent Posts
        Contact me:
        • tsou@itu.dk
        • TheoSourget
        • Théo Sourget

        Toha Theme Logo Toha
        © 2020 Copyright.
        Powered by Hugo Logo